A dialogue rather than one question
MTGBench contains seven games in Russian and English, including Wordle, Wheel of Fortune, Situation Puzzles and Alias. An episode can run for dozens of turns, forcing a model to combine new information with the conversation history. Four games use algorithmic scoring; three use an AI rule verifier that the authors checked against human annotations. The public repository includes code, datasets and model trajectories.
A single aggregate score hides the differences
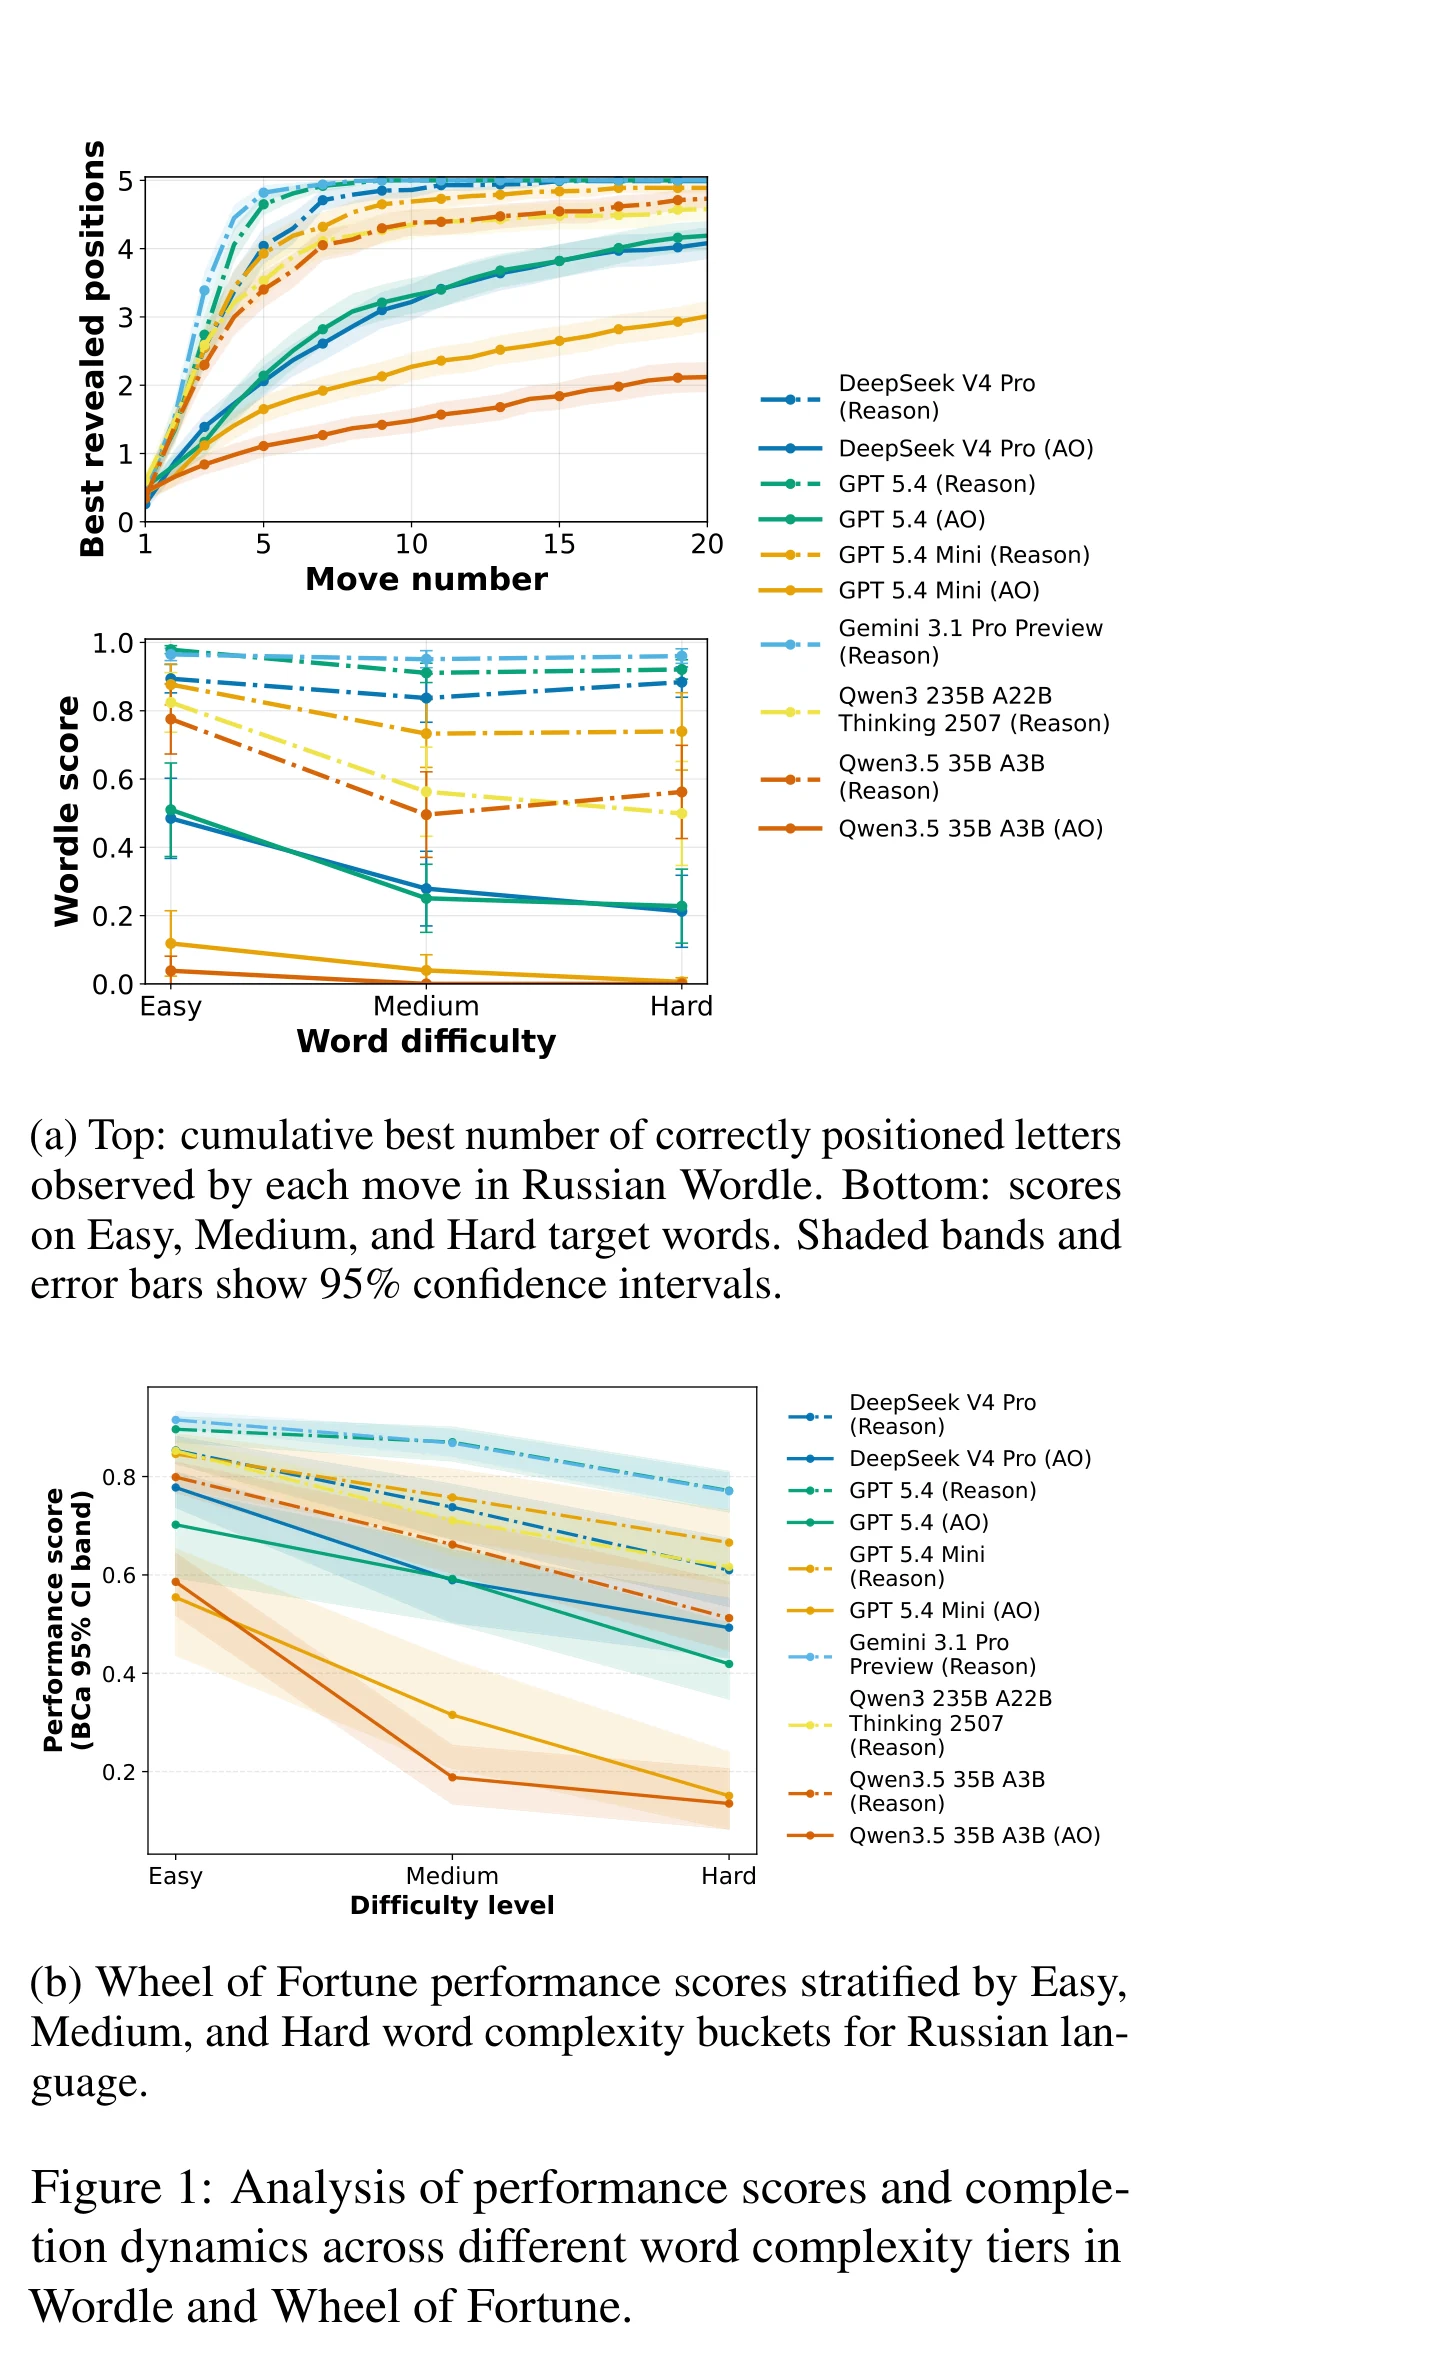
The authors evaluated 16 models. Reasoning modes helped most on letter-level tasks that require eliminating alternatives step by step, but gains were less consistent on knowledge and semantic tasks. Rankings shifted substantially between games, and Russian versions were generally harder for the systems than English ones. That matters when a team selects a model for support, document analysis or planning: a headline benchmark score is not a substitute for testing a dialogue that resembles the intended workflow.
Sources
- Yandex — Yandex and YSDA release MTGBench as open source · 27 October 2026